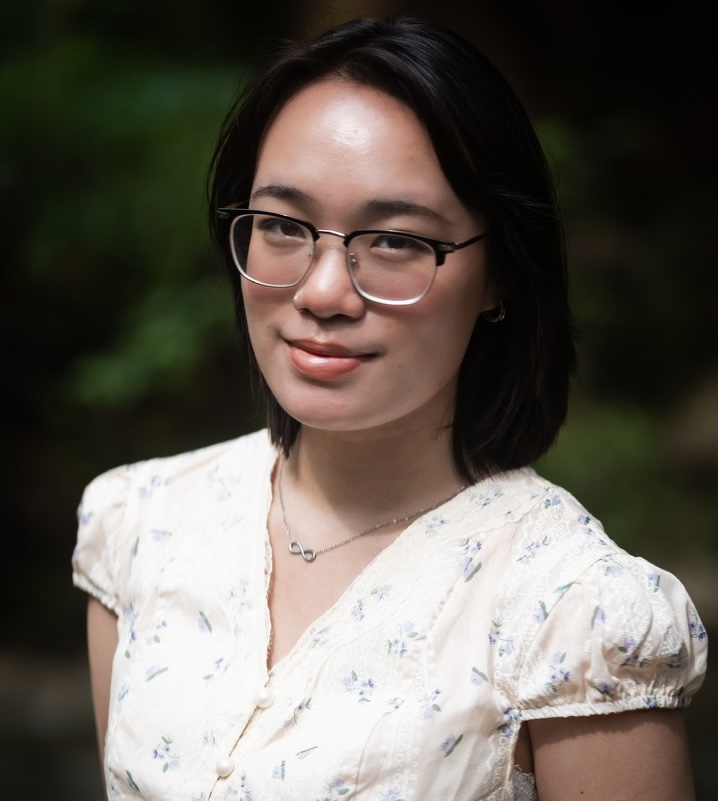


Thao Amelia Pham
I work on problems of multi-agent safety and security, especially concerning loss-of-control from unsafe interactions between multi-agent advanced AI agents. My current research focuses on red-teaming AI agent swarms in the wild to detect attacks that undermine current monitoring techniques in internal deployment settings.
I'm also broadly interested in generalization of misalignment in multi-agent RL training, and how to detect increasingly covert actions and reward hacking behaviors to robustly scale oversight.
Connect with me via my email.
Updates
Research
Selected publications and on-going projects
Red-Teaming Multi-Agent Attacks for Loss-of-Control Risks
Preprint 2026. Under review
Reciprocal Wireheading Undermines Alignment Properties in Multi-Agent LLMs Evaluations
AI4GOOD, FAST, MetaAgent @ NeurIPS 2026
GT-HarmBench: Benchmarking AI Safety Risks Through the Lens of Game Theory
*Equal Contribution. The Fortieth Annual Conference on Neural Information Processing Systems (NeurIPS), 2026
Scheming Ability in LLM-to-LLM Strategic Interactions
LaMAS @ AAAI-26, Jan 2026
Chain of Thought Still Thinks Fast: APriCoT Helps with Thinking Slow
Cognitive Science Society (CogSci), Apr 2025
The Base-Rate Effect on LLM Benchmark Performance: Disambiguating Test-Taking Strategies From Benchmark Performance
Empirical Methods in Natural Language Processing (EMNLP), Sep 2024
Large Language Model Recall Uncertainty is Modulated by the Fan Effect
Computational Natural Language Learning (CoNLL), Sep 2024
Writing
incoming